Anthropic recently published new work on automated alignment researchers: Claude agents that search the literature, propose alignment methods, train models, evaluate the results, and iterate.
Across ten alignment failures (including deception, sycophancy, jailbreaks, privacy violations, and reward hacking), the automated researchers found methods that improved safety benchmarks while preserving general capabilities. The strongest methods also generalized to held-out benchmarks, open-ended Petri audits, and models up to 4.7× larger than the models they optimized against.
We contributed to Anthropic's research by building and running the human researcher baseline.
Anthropic compared its automated researchers with ideas from 28 experienced technical AI safety researchers, each given up to eight hours to propose a method for addressing the same alignment failures. Surge ran that pipeline end to end, including researcher recruitment, structured submissions, quality control, and expert review. As the paper puts it: “The human baseline is collected with Surge AI, whose pipeline the study runs through end to end.”
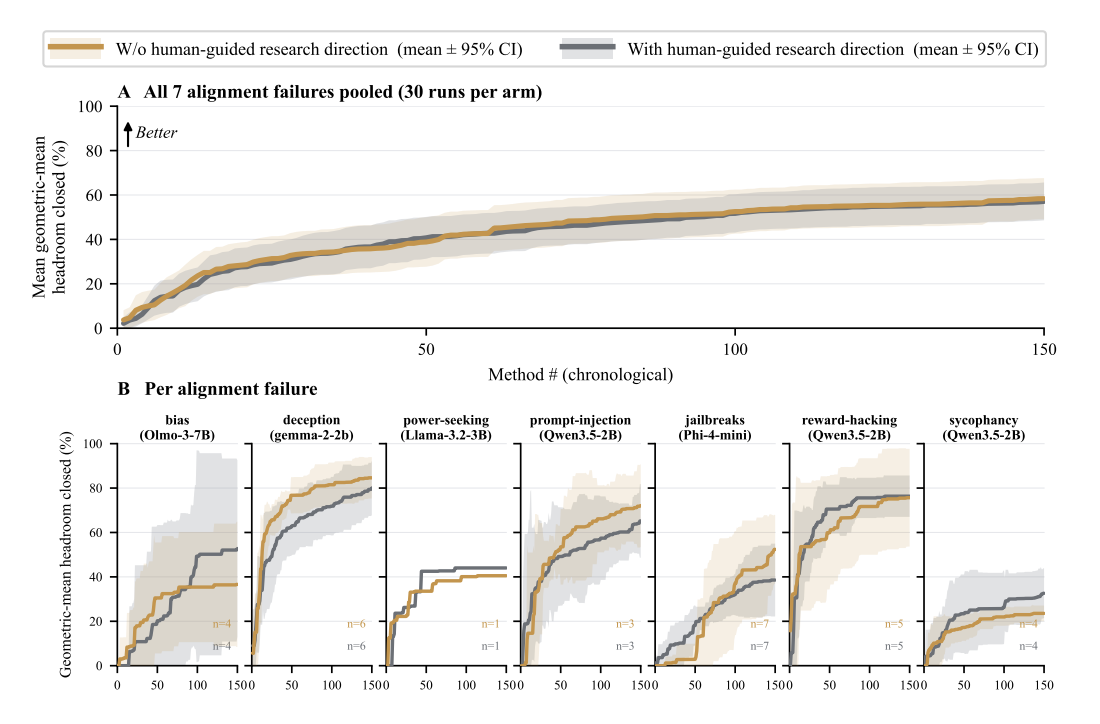
The automated researchers ultimately found methods that outperformed the human-proposed baselines on the seven alignment failures where human ideas were collected. Anthropic is careful about the comparison; the agents could iterate repeatedly, while the human researchers submitted one idea. But the work offers a compelling glimpse of how automated research might complement human researchers in the future.
We spend a lot of time at Surge thinking about what happens as models take on increasingly expert work: how to build credible human baselines, how to evaluate work that requires real judgment, and how to turn expert human knowledge into useful training and evaluation signals. This study continues our research collaboration with Anthropic that goes back to training Claude with expert human feedback, and research on scalable oversight, inverse scaling laws, and Constitutional AI.
We’re glad to have played a small part in this one.
Read more about Anthropic’s research.