

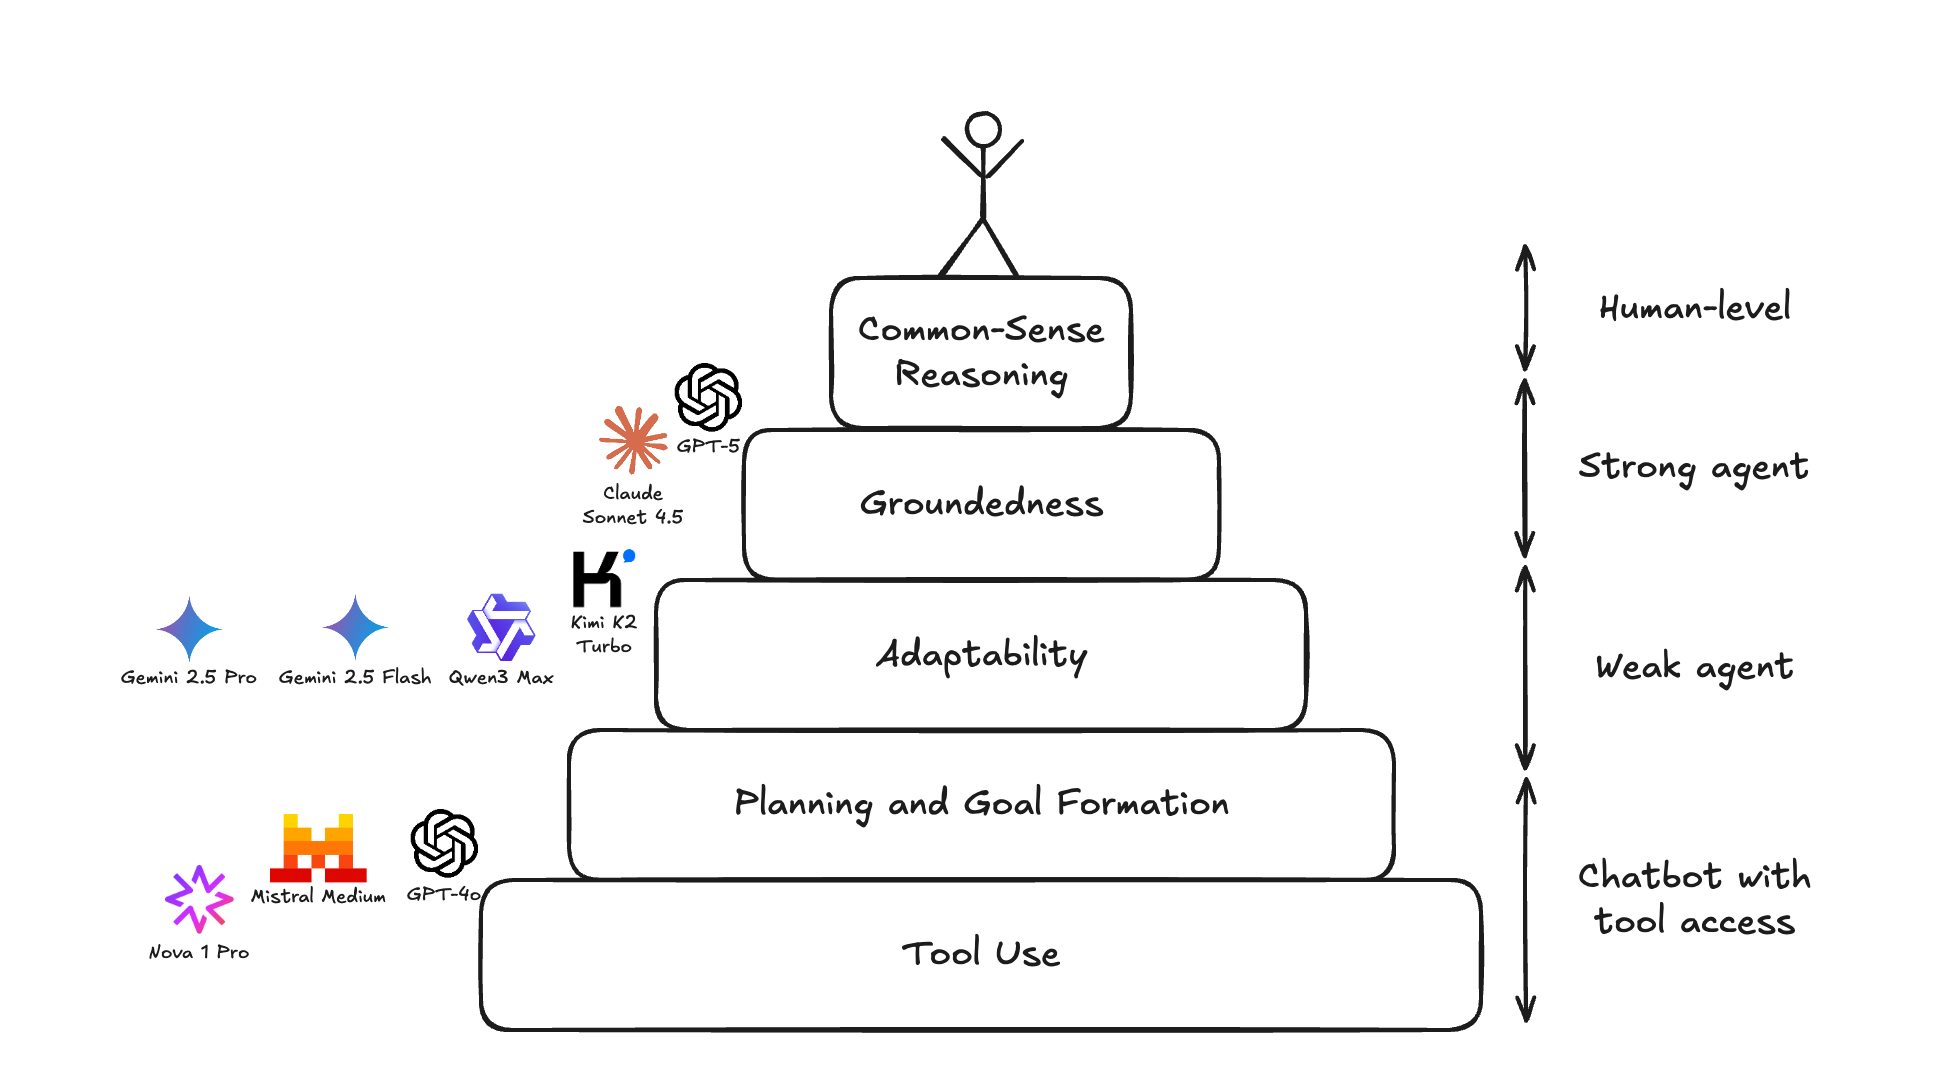

RL Environments and the Hierarchy of Agentic Capabilities
Our RL environment run on 9 models revealed the core capabilities all agents need to master: tool use, planning, adaptability, groundedness, and common sense.
We evaluate AI models on advanced mathematical problems requiring deep reasoning and novel synthesis. Our benchmark features cutting-edge problems sourced from leading mathematicians, including Ivy League professors, PhD IMO medalists, and graduate students at the top of their field.
Measuring long-horizon legal agents across contract review, due diligence, research memos, regulatory filings, and litigation support. Rather than telling models exactly what to do, it asks whether agents can work out what a client actually needs and carry the matter through to a usable work product.
DAYJOB: Tax puts agents to work on 50 professional tax assignments spanning 1,789 files: individual returns, partnerships, estates, international taxation, and more. Agents must investigate client records, identify issues the client may have overlooked, and produce reliable tax work. The strongest model, Claude Sonnet 5.5, passes 10.8% of attempts at a 95% rubric threshold.
A spreadsheet might hold a company’s financial model, a laboratory’s results, or an engineer’s calculations. GDP.xlsx puts models to work inside these files, testing whether they can follow the evidence across a workbook and produce answers a professional could rely on.
DAYJOB: Healthcare evaluates long-horizon healthcare agents across clinical, operational, payer, pharmacy, and compliance workflows. Rather than telling models exactly what to do, it asks whether agents can figure out what needs to be done, and reason through it until the end.
DAYJOB: Finance measures long-horizon finance agents across corporate finance, banking, credit, investing, and real assets. It's built around the messy reality of knowledge work: realistic requests, complex environments, and end-to-end professional judgment.
Coding agents are getting very good at being L3s. But do they have the judgment to become L7s? Across 60 tasks, agents must navigate unfamiliar systems, choose architectures, spot hidden risks, and know when technically correct code is still the wrong thing to ship.