New Frontier data and RL environments, off the shelf

Professional Graphical Reasoning

Chartography

Chartography is our benchmark for professional chart understanding. It tests whether frontier models can read the Kaplan-Meier curves, candlestick charts, contour maps, Sankey diagrams, Bode plots, and other specialized graphics that professionals use to make real decisions every day. It evaluates visual perception, domain-aware interpretation, and multi-step graphical reasoning.
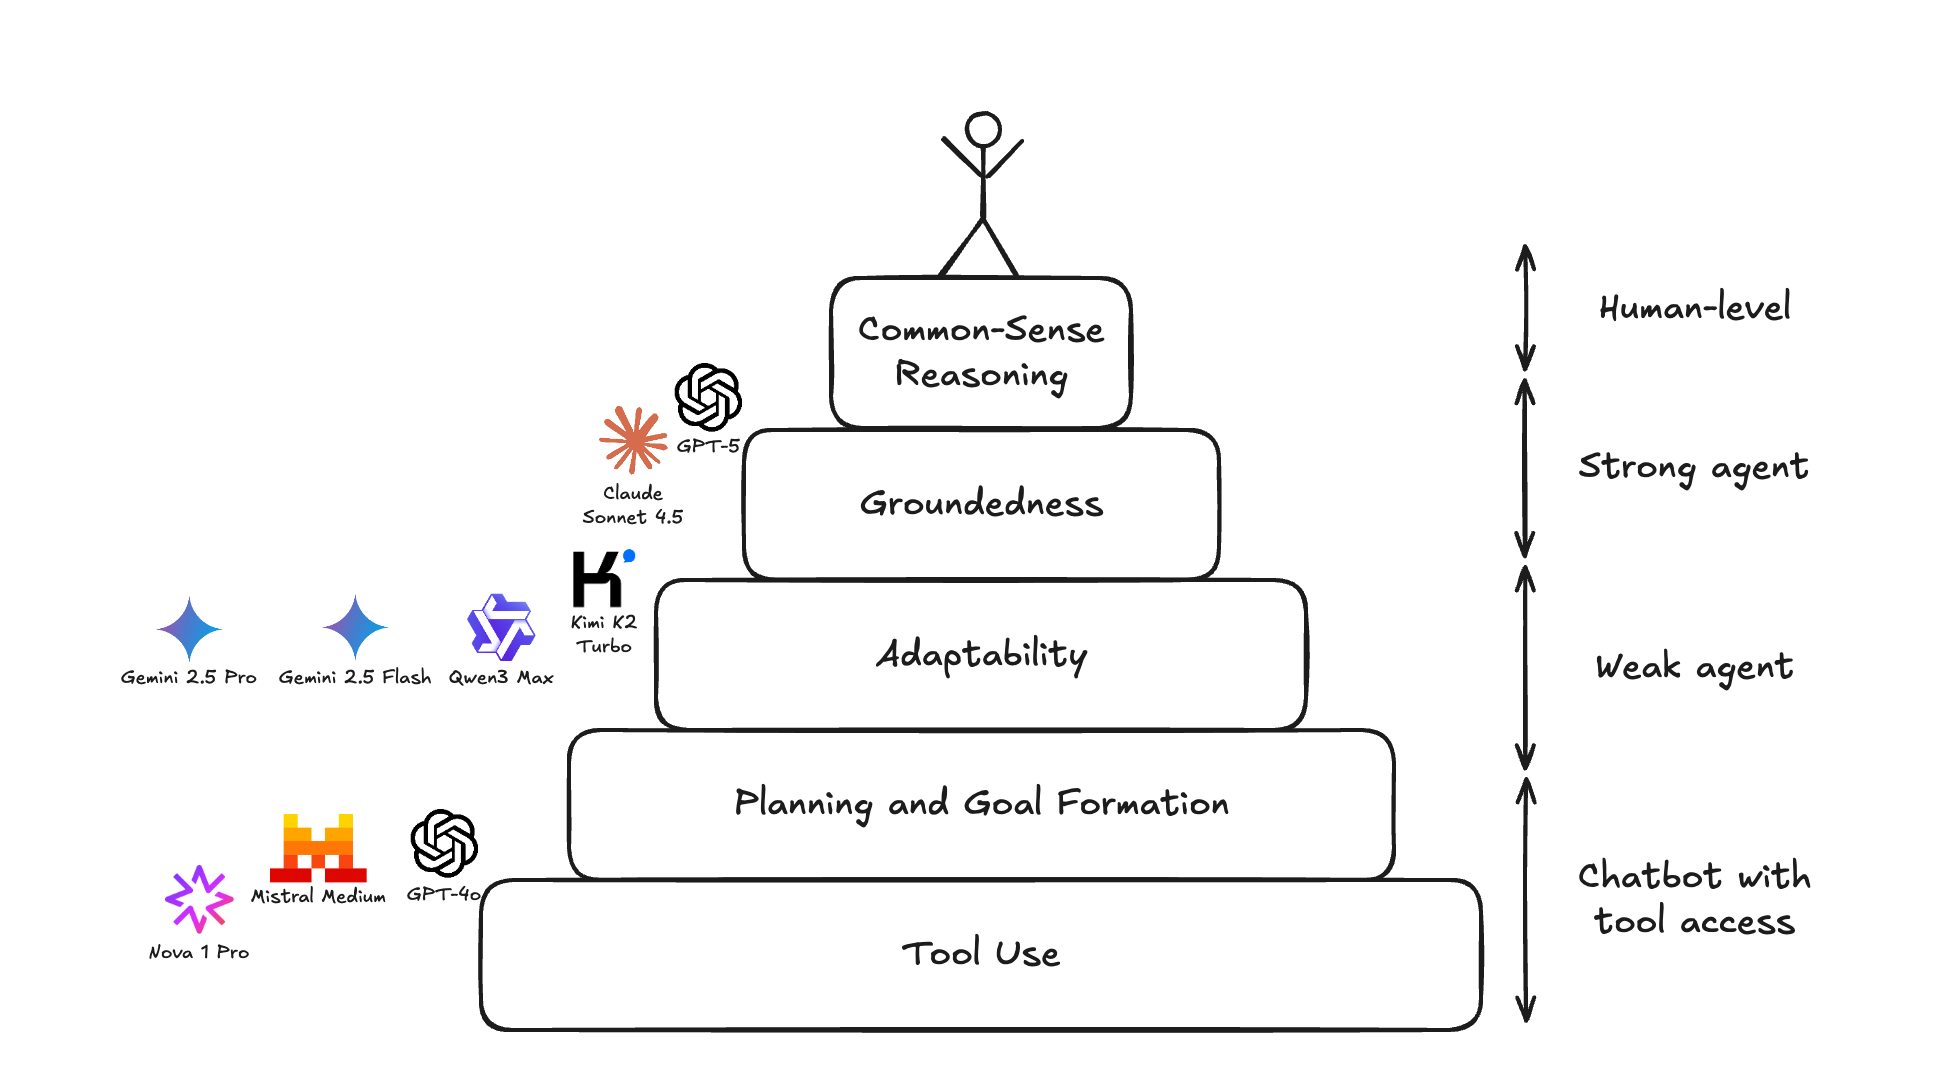
RL Environments and the Hierarchy of Agentic Capabilities
Our RL environment run on 9 models revealed the core capabilities all agents need to master: tool use, planning, adaptability, groundedness, and common sense.
Chartography Leaderboard
1
Gemini
4 Argon (High reasoning)
71.6
%
1
GPT
6 Astra (Max reasoning)
71
%
1
Claude
Opus 5.5 (Adaptive/Max)
66.3
%
1
GPT
6 Sol (Max reasoning)
53.6
%
1
Claude
Fable 5.1 (Adaptive/Max)
46.2
%
1
GPT
5.6 Sol (Max reasoning)
45
%
1
Gemini
3.8 Flash (High reasoning)
40.9
%
1
Gemini
3.7 Flash (High reasoning)
40.4
%
1
Claude
Fable 5 (Adaptive/Max)
34.8
%
1
Gemini
3.6 Flash (Medium reasoning)
34
%
1
GPT
5.6 Terra (Max reasoning)
34
%
1
Muse
Spark 1.2 (xHigh reasoning)
32.1
%
1
GPT
5.6 Luna (Max reasoning)
31.4
%
1
GPT
5.5 (xHigh reasoning)
31
%
1
GPT
5.4 (xHigh reasoning)
29.6
%
1
GPT
6 Luna (Max reasoning)
29.1
%
1
Qwen
3.8 Max (xHigh reasoning)
29.1
%
1
Muse
Spark 1.3 (xHigh reasoning)
27.6
%
1
Claude
Opus 5 (Adaptive/Max)
27.3
%
1
Kimi
K3 (Max reasoning)
26.6
%
1
Gemini
3.1 Pro (High reasoning)
26.1
%
1
Muse
Spark 1.1 (xHigh reasoning)
24.4
%
1
Grok
4.6 (xHigh reasoning)
20.5
%
1
Qwen
3.8 Flash (xHigh reasoning)
17.4
%
1
Muse
Glimmer 30B (xHigh reasoning)
17.2
%
1
Grok
4.5 (High reasoning)
17
%
1
Claude
Sonnet 5 (Adaptive/Max)
16.6
%
1
Claude
Opus 4.7 (Adaptive/Max)
16.5
%
1
GLM
5.3 Flash (Max reasoning)
16.3
%
1
Claude
Opus 4.8 (Adaptive/Max)
15.9
%
1
Qwen
3.5 Plus (Thinking on)
15.9
%
1
Qwen
3.7 Plus (Thinking on)
15.8
%
1
Grok
4.7 (xHigh reasoning)
14.7
%
1
Grok
4.3 (High reasoning)
12.9
%
1
Kimi
K2.5 (Thinking on)
12.6
%
1
Kimi
K2.6 (Thinking on)
12.2
%
1
DeepSeek
V4.1 Flash (Max reasoning)
11.6
%
1
DeepSeek
V4 Flash Vision (experimental) (Max reasoning)
11.2
%
1
Gemini
3.5 Flash-Lite (Minimal reasoning)
10.2
%
1
Inkling
Inkling (High reasoning)
10
%
1
Inkling
Small (xHigh reasoning)
9.1
%
1
Mistral
Large 3
9
%

Score vs. cost per trial

Score vs. generated tokens

Stay Posted