

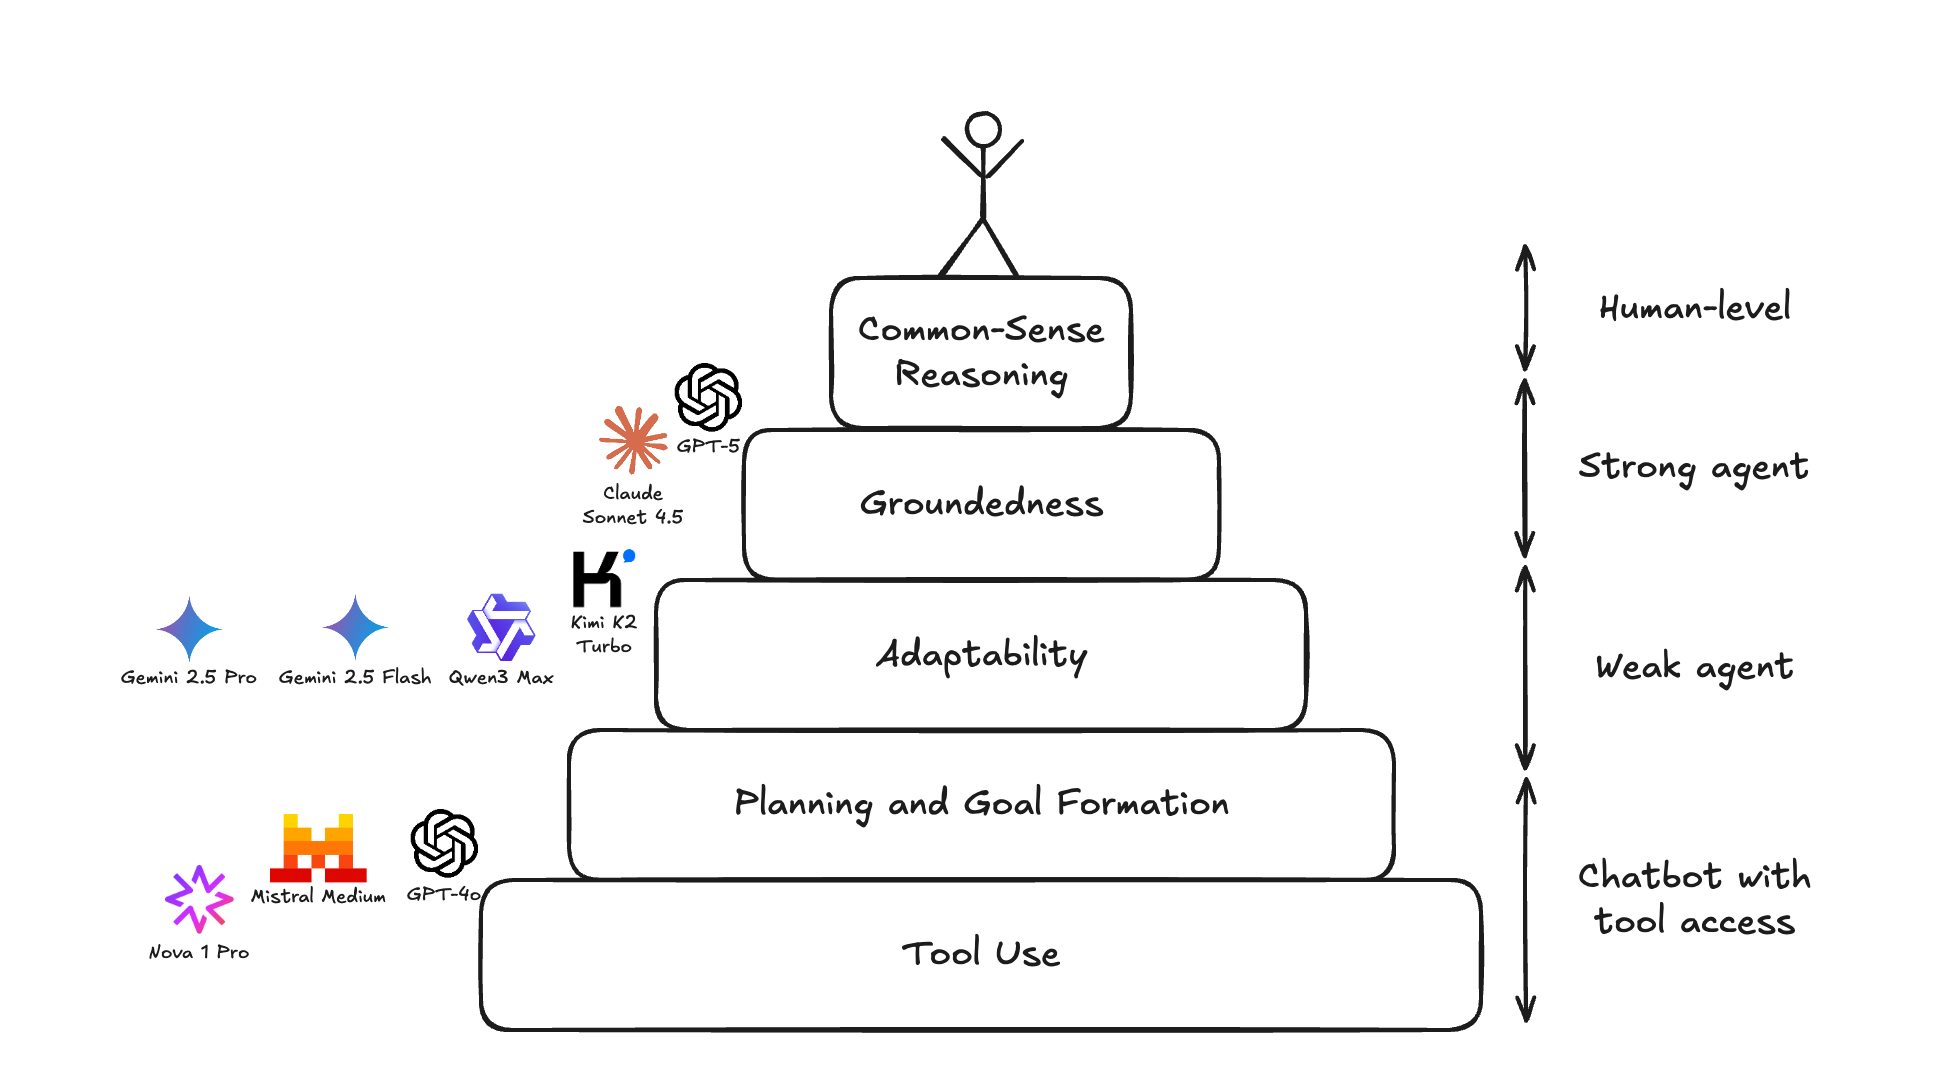

RL Environments and the Hierarchy of Agentic Capabilities
Our RL environment run on 9 models revealed the core capabilities all agents need to master: tool use, planning, adaptability, groundedness, and common sense.
Can an agent follow a 100-page company handbook inside an enterprise RL environment?
HANDBOOK.md is a benchmark for long-context agentic instruction following, modeled on how professionals follow corporate policy in their day-to-day work. Each task is a unique RL environment with internal tools and external MCP servers, across five enterprise domains.
DAYJOB: Tax puts agents to work on 50 professional tax assignments spanning 1,789 files: individual returns, partnerships, estates, international taxation, and more. Agents must investigate client records, identify issues the client may have overlooked, and produce reliable tax work. The strongest model, Claude Sonnet 5.5, passes 10.8% of attempts at a 95% rubric threshold.
Coding agents are getting very good at being L3s. But do they have the judgment to become L7s? Across 60 tasks, agents must navigate unfamiliar systems, choose architectures, spot hidden risks, and know when technically correct code is still the wrong thing to ship.
DAYJOB: Finance measures long-horizon finance agents across corporate finance, banking, credit, investing, and real assets. It's built around the messy reality of knowledge work: realistic requests, complex environments, and end-to-end professional judgment.