New Frontier data and RL environments, off the shelf

Creative, Business, and Everyday Writing

Hemingway-bench

Most AI writing benchmarks reward surface-level signals: elaborate metaphors and prose that looks impressive at a glance. Hemingway-bench rewards writing that is actually good.

Our leaderboard is judged by professional writers who evaluate creative writing, business writing, and everyday writing tasks for taste, originality, coherence, and emotional intelligence.
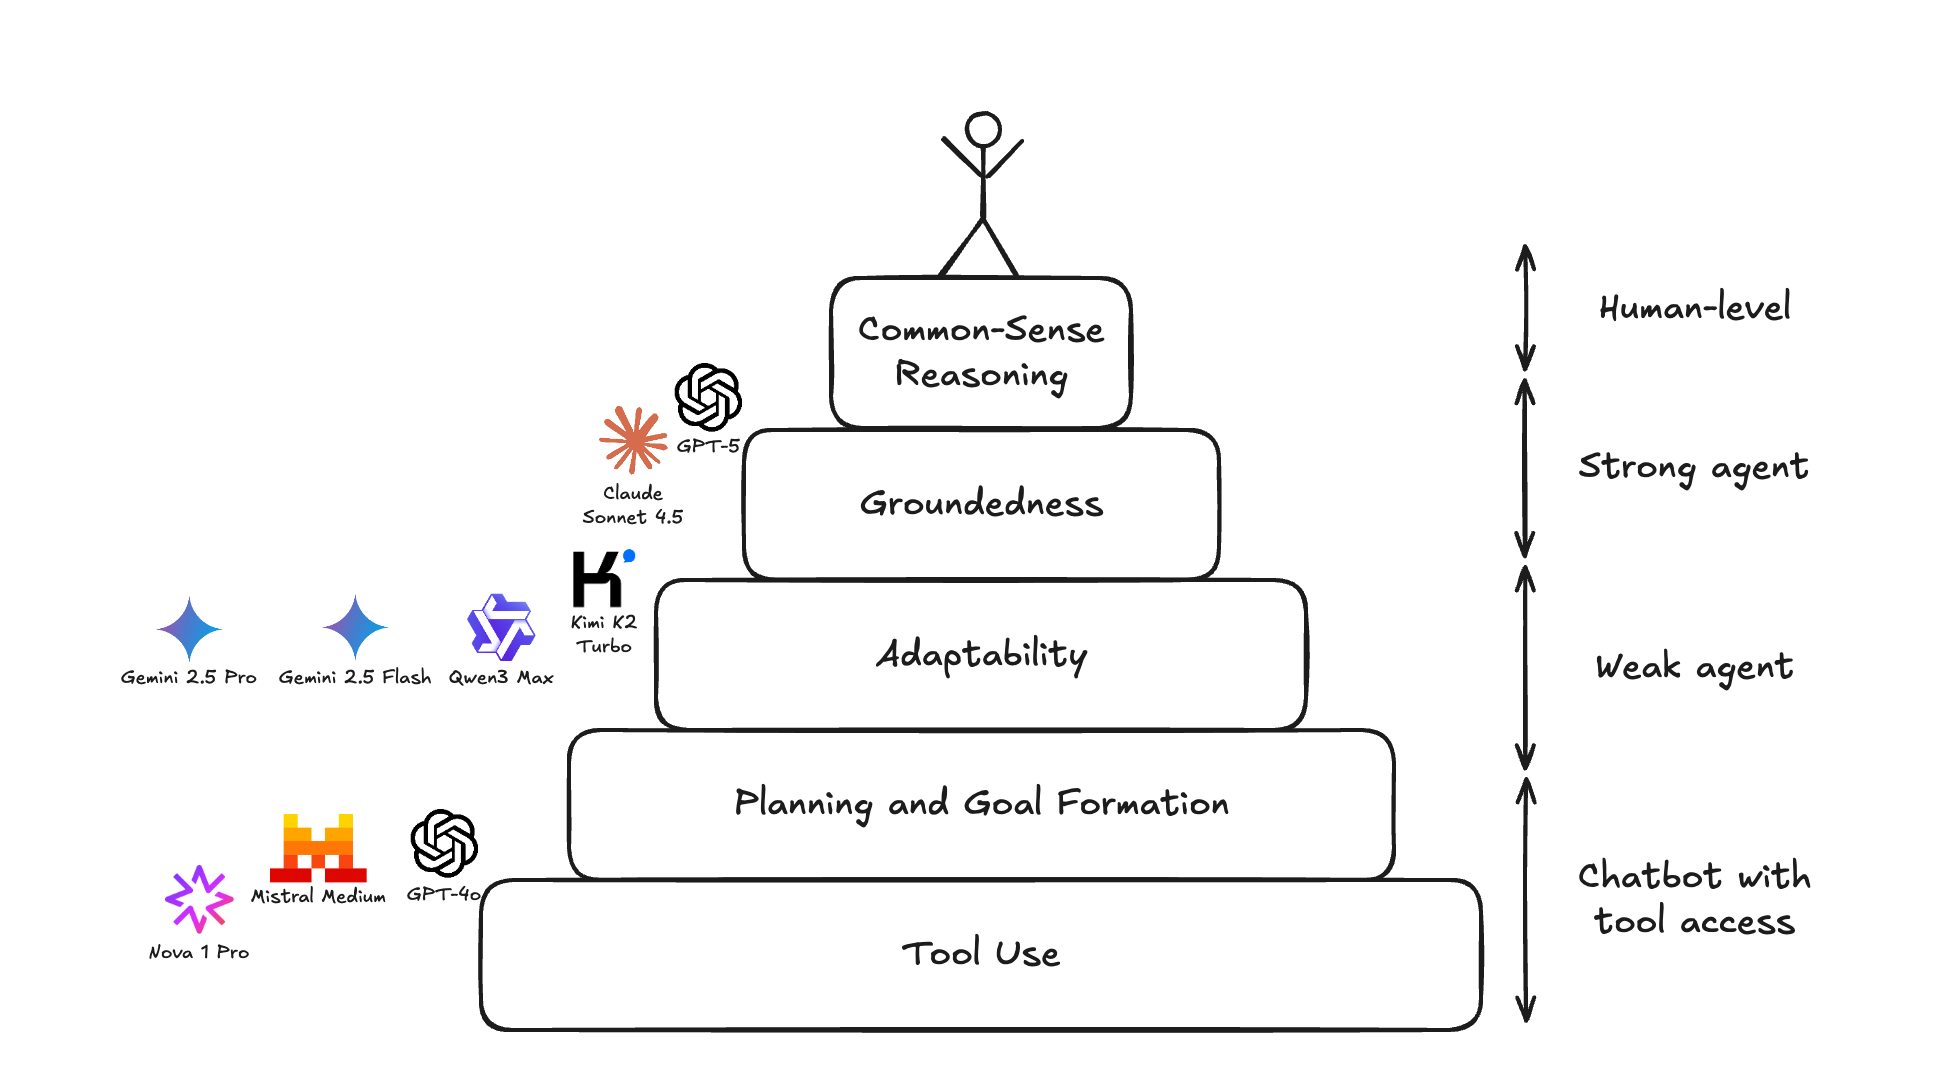
RL Environments and the Hierarchy of Agentic Capabilities
Our RL environment run on 9 models revealed the core capabilities all agents need to master: tool use, planning, adaptability, groundedness, and common sense.
Hemingway-bench Leaderboard
1
Claude
Fable 5 (Adaptive/High)
1110
1091
 - 
1130
2
Gemini
3.7 Flash (Medium reasoning)
1105
1084
 - 
1126
3
Claude
Fable 5.1 (Adaptive/High)
1095
1071
 - 
1118
4
Gemini
3.8 Flash (Medium reasoning)
1093
1069
 - 
1117
5
Gemini
3.6 Flash (Medium reasoning)
1075
1055
 - 
1095
6
Gemini
3.1 Pro (High reasoning)
1073
1057
 - 
1088
7
Gemini
3.5 Flash (Medium reasoning)
1071
1054
 - 
1088
8
Kimi
K3 (Max reasoning)
1069
1049
 - 
1089
9
GPT
5.6 Sol (Medium reasoning)
1057
1037
 - 
1076
10
Gemini
3 Pro (High reasoning)
1056
1031
 - 
1081
11
GLM
5.3 (Max reasoning)
1053
1030
 - 
1076
12
Gemini
3 Flash (High reasoning)
1052
1037
 - 
1066
13
Claude
Opus 5 (Adaptive/High)
1047
1026
 - 
1068
14
DeepSeek
V4 Pro (High reasoning)
1046
1025
 - 
1068
15
Claude
Opus 4.6 (High reasoning)
1045
1029
 - 
1061
16
Claude
Opus 4.8 (Adaptive/Default/High)
1044
1026
 - 
1061
17
Claude
Opus 4.7 (High reasoning)
1042
1026
 - 
1058
18
Claude
Opus 4.8 (High reasoning)
1038
1021
 - 
1055
19
GLM
5.2 (Auto reasoning)
1036
1019
 - 
1053
20
GPT
5.5 (Medium reasoning)
1035
1019
 - 
1052
21
GLM
5.3 Flash (Max reasoning)
1034
1010
 - 
1057
22
Kimi
K2.6 (Thinking on)
1021
1004
 - 
1038
23
Claude
Opus 4.5 (High reasoning)
1016
995
 - 
1037
24
Hy
Hy4 Preview (High reasoning)
1014
991
 - 
1037
25
Muse
Spark 1.2 (Auto reasoning)
1013
992
 - 
1034
26
Qwen
3.8 Max (xHigh reasoning)
1009
988
 - 
1030
27
Claude
Sonnet 4.6 (High reasoning)
1001
985
 - 
1016
28
DeepSeek
V4 Pro (preview) (High reasoning)
999
982
 - 
1015
29
GPT
5.2 Chat
994
978
 - 
1010
30
Gemini
3.5 Flash-Lite (Minimal reasoning)
990
970
 - 
1010
30
Qwen
3.5 Plus (Thinking on)
990
974
 - 
1005
32
Kimi
K2.5 (Thinking on)
988
973
 - 
1003
33
Muse
Spark 1.1 (Medium reasoning)
985
966
 - 
1005
33
GPT
5.4 (No reasoning)
985
969
 - 
1001
35
Grok
4.6 (High reasoning)
983
962
 - 
1004
36
DeepSeek
V4 Flash Vision (experimental)
981
958
 - 
1003
37
Grok
4.5 (High reasoning)
972
954
 - 
991
38
Hy
Hy3 (No reasoning)
971
949
 - 
994
39
DeepSeek
V4 Flash (preview) (High reasoning)
969
953
 - 
986
40
GPT
5.2 (No reasoning)
954
929
 - 
980
41
Qwen
3 Max (No reasoning)
948
920
 - 
975
42
Qwen
3.8 Flash (xHigh reasoning)
929
905
 - 
952
43
Grok
4.1 Fast Reasoning (Thinking on)
916
901
 - 
931
44
Muse
Glimmer 30B (High reasoning)
913
892
 - 
935
45
Nemotron
Lightning 3.5 30B A3B (Thinking on)
888
866
 - 
911
46
Kimi
K2 Instruct
883
856
 - 
910
47
Llama
4 Maverick
803
781
 - 
824
48
Nova
2 Pro (No reasoning)
749
718
 - 
779

Stay Posted